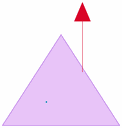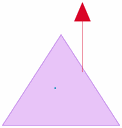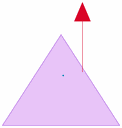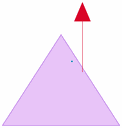
Policy Gradient
Chapter 15: Bellman Equations and Operators — Policy Gradient Theorem & Stochastic Approx.
From the book
Chapter 15: Bellman Equations and Operators. In the chapter mind map this icon labels Policy Gradient Theorem & Stochastic Approx.. The discussion below is excerpted and lightly edited from § Policy Gradient Theorem & Stochastic Approx. in Mathematics for AI and Machine Learning.
The gradient of the expected return with respect to policy parameters is:
where $\mu^{\pi_\theta}$ is the stationary state distribution under policy $\pi_\theta$.
For the infinite-horizon case with discounting, this becomes:
where $d_{\pi_\theta}(s) = (1-\gamma) \sum_{t=0}^{\infty} \gamma^t \mu_t(s)$ is the discounted state visitation distribution.
What this drawing shows
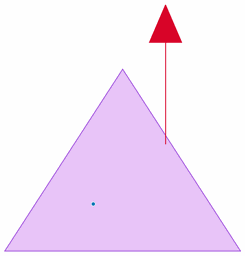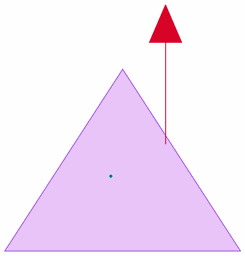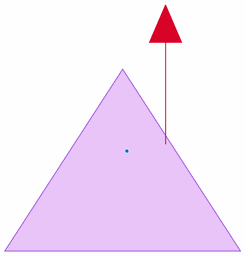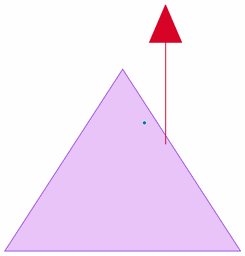
What you see. Purple policy simplex $\pi_\theta$ and red $\nabla_\theta J$ arrow fixed; a blue policy parameter moves uphill along the gradient update.
In the mind map. Chapter 15 — Policy Gradient Theorem & Stochastic Approx.. See From the book above for definitions, figures, and worked examples.
Where to read next
Read the full definitions, figures, and worked examples in Chapter 15: Bellman Equations and Operators — see the mind-map node Policy Gradient Theorem & Stochastic Approx..