Trust Region
Chapter 15: Bellman Equations and Operators — Trust Region Methods (TRPO) & Natural PG
From the book
Chapter 15: Bellman Equations and Operators. In the chapter mind map this icon labels Trust Region Methods (TRPO) & Natural PG. The discussion below is excerpted and lightly edited from § Definition: Trust Region Constraint in Mathematics for AI and Machine Learning.
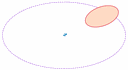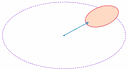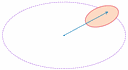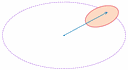
A trust region constraint limits policy updates to a neighborhood of the current policy. For policies parameterized by $\boldsymbol\theta$, a trust region constraint can be expressed as:
where $\delta > 0$ is the trust region radius and $D_{\mathrm{KL}}$ is the KL divergence (see the matrix chapter).
What this drawing shows
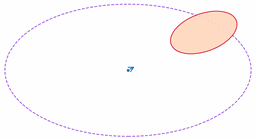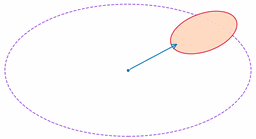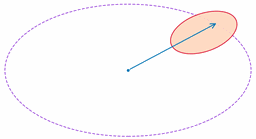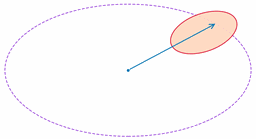
What you see. KL trust-region ellipse fixed; blue policy step grows then clips inside the region.
In the mind map. Chapter 15 — Trust Region Methods (TRPO) & Natural PG. See From the book above for definitions, figures, and worked examples.
Where to read next
Read the full definitions, figures, and worked examples in Chapter 15: Bellman Equations and Operators — see the mind-map node Trust Region Methods (TRPO) & Natural PG.